What Are the Common Failure Modes in Legacy Industrial Control Systems?
A production line stops without a clear mechanical fault, a temperature reading slowly moves away from the actual process, or an operator screen freezes while equipment continues running. The common failure modes in legacy industrial control systems include unstable power, deteriorating connections, failing PLC and I/O hardware, sensor drift, actuator problems, communication interruptions, software incompatibility, and loss of recoverable configurations. Their effects range from nuisance alarms and rejected product to uncontrolled process conditions.
The first task is to distinguish the failed component from the system reporting the failure. A PLC fault may originate in its power supply; a network timeout may reflect a controller restart; an apparently defective sensor may have a damaged cable. Start with the event sequence, check shared dependencies, and preserve diagnostic evidence before replacing equipment or restarting the system.
Recognize the failure pattern before opening the cabinet
Legacy does not automatically mean unreliable. The greater concern is a system whose operating condition, documentation, replacement parts, or recovery tools are no longer well controlled. Older equipment can remain serviceable, but troubleshooting becomes difficult when intermittent faults combine with undocumented changes.
Identify the scope of the disturbance. One drifting measurement suggests a local instrumentation problem. Several unrelated inputs failing simultaneously point toward shared power, grounding, an I/O rack, or a communications link. Problems that appear only during motor starts or after the cabinet heats up warrant a different investigation from faults that begin immediately after maintenance.
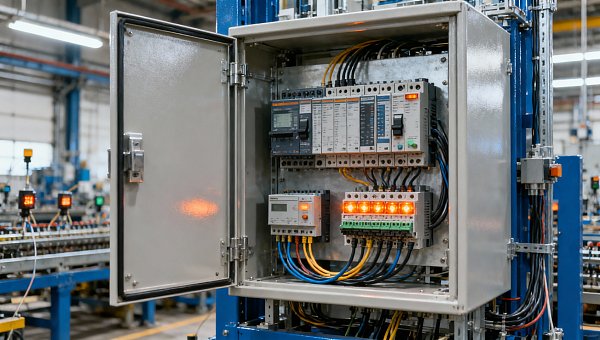
Power and environmental faults often masquerade as controller failures
Unstable control power
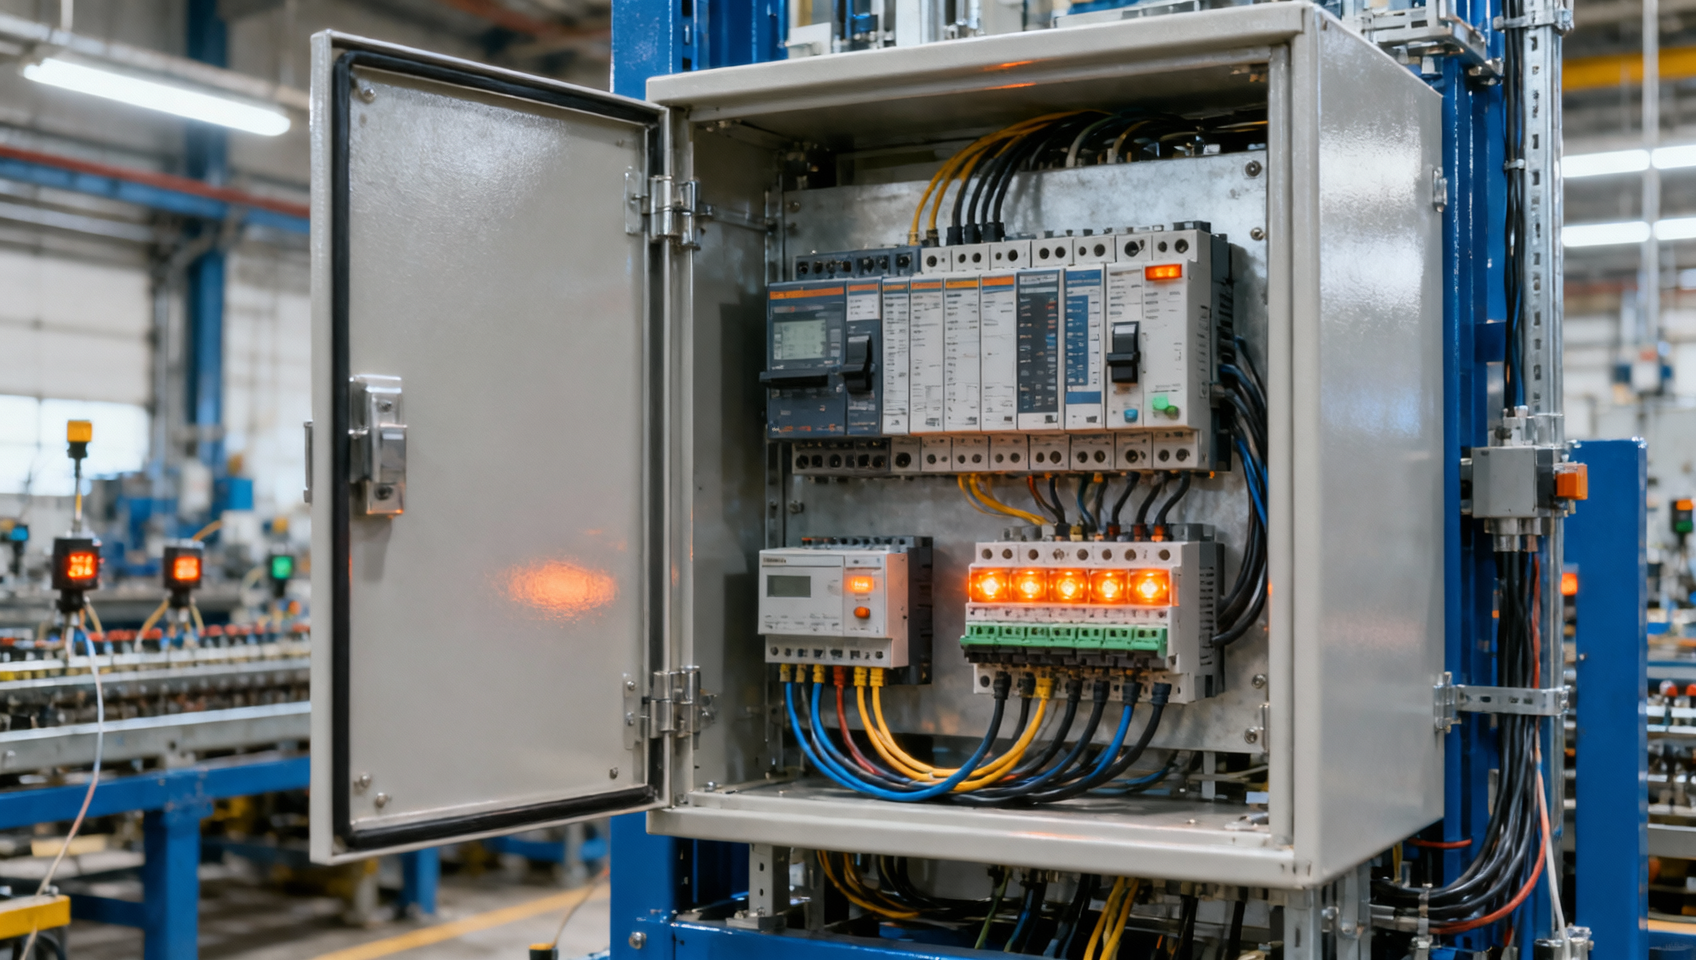
Aging power supplies can develop degraded capacitors, excessive ripple, or reduced load capacity. Loose supply connections, overloaded circuits, and upstream voltage disturbances can produce similar symptoms. The controller may restart, remote I/O may disconnect, or contactors may chatter even though the application program is unchanged.
A voltage reading taken while the machine is idle may miss the problem. Qualified personnel should assess the supply under relevant operating conditions and, where appropriate, capture transient behavior with suitable instruments. Compare results with the equipment manufacturer’s limits rather than assuming that a nominal voltage reading proves the supply is healthy.
Replace a confirmed defective supply with one that meets the actual electrical, environmental, and load requirements. Before increasing capacity, investigate unexpected current demand: a damaged field device or wiring fault can overload a replacement supply as well.
Heat, contamination and deteriorating connections
Blocked filters, failed cabinet fans, oil mist, moisture, and conductive dust can undermine otherwise functional electronics. Thermal problems may appear only after prolonged operation or during warmer conditions. Corrosion and loose terminals can create intermittent resistance changes that affect both power and low-level signals.
Review cabinet temperature, cooling operation, seals, cable entries, and visible contamination. De-energized inspections can reveal damaged insulation, discolored terminals, or deteriorated connectors. Cleaning methods must suit the electronics; uncontrolled compressed air or unsuitable solvents can spread contamination or damage components.
Grounding and shielding deserve separate attention when faults correlate with drives, welding equipment, or switching loads. Do not alter protective grounding or shield connections by trial and error. Check the installation against the device documentation and the site’s electrical design.
Failures within PLCs, I/O and field equipment
Controller memory, batteries and aging modules
Some older controllers use batteries to retain memory or maintain a clock. A battery warning may precede program loss after a shutdown, although the exact behavior depends on the controller design. Other systems rely on nonvolatile memory or removable storage, which introduce different failure and recovery requirements.
Watchdog faults, repeated processor errors, intermittent backplane connections, and isolated channel failures can also occur. However, a watchdog event is not proof of failed hardware: software execution problems or excessive task loading may trigger it. Read the diagnostic code and preserve the fault history before drawing conclusions.
Before replacing a CPU or I/O module, verify the catalog number, hardware revision, firmware, rack compatibility, and configuration requirements. A physically compatible module may still behave differently. Battery replacement procedures also vary; follow the manufacturer’s instructions and maintain a verified backup rather than assuming retention will be uninterrupted.
Sensor drift and signal-path degradation
A drifting measurement can cause the controller to make the wrong decision while appearing to operate normally. Temperature probes, pressure transmitters, level instruments, and position sensors may deteriorate through contamination, mechanical damage, or changing process conditions. Cable resistance, moisture ingress, and signal conditioning faults can produce comparable errors.
Compare the process value with an independent reference suitable for the measurement. Then separate the measurement chain: sensing element, transmitter output, field wiring, input module, and software scaling. For an analog loop, distinguish an incorrect transmitter signal from a correct signal interpreted incorrectly by the controller.
Calibration is appropriate only after establishing that the instrument and signal path are stable. Adjusting a drifting instrument to compensate for damaged wiring can hide the fault. Record both the as-found and as-left condition so recurring deterioration remains visible.
Outputs and actuators that fail to follow commands
Worn relay contacts, failed output channels, sticking valves, drive faults, and inadequate pneumatic or hydraulic pressure can prevent a commanded action. An HMI indicator may show that software requested motion, not that motion occurred. This distinction matters when a sequence waits indefinitely or proceeds using unreliable feedback.
Trace the command through permissives and interlocks, the output channel, the interface device, and the actuator. Confirm physical response using independent feedback where available. Repeated relay or solenoid failures may indicate excessive switching duty, unsuitable ratings, or missing or defective suppression rather than random component wear.
Communication and software failures can leave hardware looking healthy
Communication faults commonly involve damaged cables, deteriorated connectors, incorrect serial settings, improper termination on networks that require it, electromagnetic interference, or inconsistent device configuration. Industrial Ethernet systems may also suffer from failing switches, address conflicts, or traffic conditions their original design did not anticipate.
Start with node diagnostics and error counters. Determine whether one device, one segment, or the entire network is affected. Check power at the affected node before attributing the fault to the network. Where possible, compare current configurations with a known-good baseline and make one controlled change at a time. Repeated resets may temporarily restore service while erasing evidence.
Unsupported software creates a different class of risk. An HMI computer can fail because of storage deterioration, application crashes, missing licenses, or incompatible operating-system changes. The PLC may continue controlling the process while operators lose visibility, alarm acknowledgement, or recipe access. Define how the process remains safe when that interface is unavailable.
Engineering workstations introduce recovery dependencies: programming software, interface adapters, project files, passwords, and compatible versions must all be available. A backup that cannot be opened or restored with the remaining tools is not a complete recovery capability.
Cybersecurity weaknesses also deserve consideration. Unsupported systems may lack security updates, while shared credentials, unnecessary remote access, or uncontrolled connections can expose them to disruption or unauthorized changes. These are not inevitable failures caused by age, but they can create an outage or obscure its cause. Use network segmentation, controlled access, and supported monitoring approaches without introducing untested scanning or software into sensitive control environments.
A practical sequence for investigating an intermittent shutdown
Intermittent faults require evidence gathered across electrical, control, and process conditions. A useful investigation follows the sequence below, adjusted to the equipment’s hazards and available diagnostics.
- Establish a safe condition. Follow site isolation and lockout procedures before intrusive work. Keep safety functions intact; bypassing an interlock to reproduce a fault can create a greater hazard than the original problem.
- Preserve the sequence. Collect controller faults, HMI alarms, drive events, operator observations, and recent maintenance records. Check clock alignment: the first displayed alarm may not be the initiating event.
- Look for a shared dependency. Compare affected devices by power supply, cabinet, rack, network segment, and process condition. Several simultaneous failures usually justify investigating their common infrastructure first.
- Test a specific hypothesis. Choose a measurement or inspection that can distinguish competing causes. Correlating controller restarts with supply disturbances is more useful than replacing unrelated modules speculatively.
- Verify under representative conditions. After repair, confirm operation through relevant load changes, warm-up, communications recovery, and restart behavior. Perform tests under an approved plan, not by creating uncontrolled production faults.
Live electrical measurements, controller changes, and safety-related diagnostics require appropriately qualified personnel. Do not force outputs, disconnect operational networks, or defeat protective functions simply to shorten the investigation. Any temporary diagnostic arrangement needs defined authorization, limits, and removal criteria.
Decide whether to repair, retrofit or replace
A localized failure in a documented system with available spares may justify repair. A targeted retrofit can address a failing HMI, power supply, or network component when interfaces and operating behavior can be preserved. Broader migration becomes more compelling when multiple critical components are unsupported, failures recur across the architecture, or recovery depends on unavailable tools.
Prioritize by consequence and recoverability, not equipment age alone. Consider what happens when each component fails, whether the fault is detectable, how long restoration could take, and whether a verified substitute exists. A healthy controller with no accessible program backup may present a greater continuity risk than a worn component that can be replaced safely from stock.
Procurement specifications should identify exact compatibility requirements, provenance, storage condition, support availability, and acceptance testing. Refurbished or old-stock hardware can be useful, but it is not automatically equivalent to a supported replacement. Require evidence appropriate to the component rather than relying on appearance or a matching model label.
Before a planned shutdown, confirm that backups include controller logic, HMI projects, device parameters, network settings, and required software or licenses. Validate restoration in an isolated environment where feasible. For any upgrade, define acceptance tests for scaling, timing, alarms, fail-safe behavior, and restart sequences, plus a workable rollback plan. These details turn modernization from a component purchase into a controlled recovery and reliability improvement.
Get weekly intelligence in your inbox.
No noise. No sponsored content. Pure intelligence.
 Oct 22, 2026Mitsubishi Electric Develops Industry-First Humanoid Robot–CNC Machining SystemMitsubishi Electric Develops Industry-First Humanoid Robot–CNC Machining System
 Oct 22, 2026Aerospace Aluminum Machining: How to Control Distortion in Thin-Wall PartsAerospace Aluminum Machining: How to Control Distortion in Thin-Wall Parts
 Oct 21, 2026Genesis Energy commissions 200 MWh battery storage system at HuntlyGenesis Energy commissions 200 MWh battery storage system at Huntly
 Oct 21, 2026Buying AMI Smart Meters Wholesale: Compatibility Checks and Total CostsBuying AMI Smart Meters Wholesale: Compatibility Checks and Total Costs
 Oct 20, 2026Werner Enterprises Issues Q3 Earnings Warning as Costs RiseWerner Enterprises Issues Q3 Earnings Warning as Costs Rise
 Oct 20, 2026Are Digital Twins Viable for SMEs? Costs, Use Cases, and Data RequirementsAre Digital Twins Viable for SMEs? Costs, Use Cases, and Data Requirements
 Oct 19, 2026Choosing a Wholesale Servo Motor Exporter: Traceability and Warranty ChecksChoosing a Wholesale Servo Motor Exporter: Traceability and Warranty Checks
 Oct 18, 2026Syringe Manufacturing Equipment: Evaluating Throughput and Assembly AccuracySyringe Manufacturing Equipment: Evaluating Throughput and Assembly Accuracy
 Oct 17, 2026Air Freight Forwarding Services: How to Compare Quotes for Urgent ShipmentsAir Freight Forwarding Services: How to Compare Quotes for Urgent Shipments
 Oct 16, 2026Wholesale Solar Panels: How to Compare Bulk Quotes by Total Landed CostWholesale Solar Panels: How to Compare Bulk Quotes by Total Landed Cost
 Oct 15, 2026Supply Chain Intelligence for Sourcing: How to Vet New SuppliersSupply Chain Intelligence for Sourcing: How to Vet New Suppliers
 Oct 14, 2026How skills shortages slow smart manufacturing in Southeast AsiaHow skills shortages slow smart manufacturing in Southeast Asia
 Oct 14, 2026How CNC wire-cut machining maintains tight tolerances in thick partsHow CNC wire-cut machining maintains tight tolerances in thick parts
 Oct 14, 2026Can automated feeding stabilize metal forming in smart factories?Can automated feeding stabilize metal forming in smart factories?
 Oct 14, 2026Can CT inspection detect internal defects in metal additive parts?Can CT inspection detect internal defects in metal additive parts?
 Oct 14, 2026When does additive manufacturing reduce lead time for spare parts?When does additive manufacturing reduce lead time for spare parts?
 Oct 14, 2026How production volume affects ROI on an automated painting lineHow production volume affects ROI on an automated painting line
 Oct 14, 2026What data does manufacturing bottleneck analysis consulting need?What data does manufacturing bottleneck analysis consulting need?
 Oct 14, 2026When should you hire a consultant for manufacturing bottlenecks?When should you hire a consultant for manufacturing bottlenecks?
 Oct 14, 2026How Do You Measure AI Adoption Maturity in a Traditional Factory?How Do You Measure AI Adoption Maturity in a Traditional Factory?
 Oct 14, 2026Are Chinese AI-Assisted Surgical Devices Gaining Global Trust?Are Chinese AI-Assisted Surgical Devices Gaining Global Trust?
 Oct 14, 2026What Happens When Warehouse Robots Need Software Updates Mid-Operation?What Happens When Warehouse Robots Need Software Updates Mid-Operation?
 Oct 14, 2026How Do Plants Calculate Real Savings from Energy-Efficient Equipment?How Do Plants Calculate Real Savings from Energy-Efficient Equipment?
 Oct 14, 2026Are Digital Twins Only for Large Enterprises, or Can SMEs Use Them?Are Digital Twins Only for Large Enterprises, or Can SMEs Use Them?
 Oct 14, 2026What Are the Common Failure Modes in Legacy Industrial Control Systems?What Are the Common Failure Modes in Legacy Industrial Control Systems?
 Oct 14, 2026Do Electronic Component Distributors Add Value or Just Markup?Do Electronic Component Distributors Add Value or Just Markup?
 Oct 14, 2026What ESG Requirements Apply to Solar PV Exporters Selling to Europe?What ESG Requirements Apply to Solar PV Exporters Selling to Europe?