Does Predictive Maintenance Work Across Equipment from Different Vendors?
Does Predictive Maintenance Work Across Equipment from Different Vendors?
Does predictive maintenance technology work well on equipment from different vendors? Yes—but a shared dashboard is not proof that a system can make reliable maintenance predictions. For manufacturers managing mixed fleets, success depends on access to useful signals, consistent data definitions, equipment-specific validation, and a practical route from an alert to a maintenance decision.
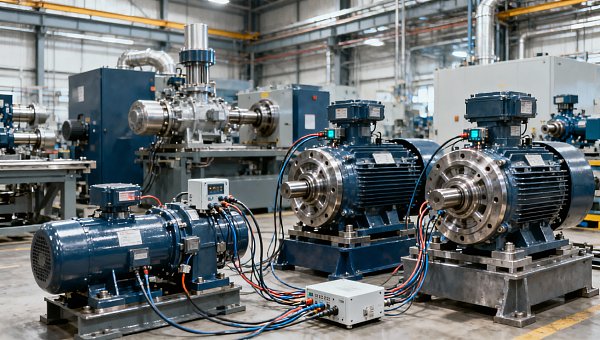
A plant may operate machining centers from one supplier, compressors from another, and older pumps with no digital interface at all. Bringing these assets into one monitoring environment is possible. Treating them as though they behave identically is where projects become unreliable.
The useful question is therefore not simply whether a platform supports multiple brands. It is whether it can detect the failure modes that matter on your equipment, early enough for your team to act, without creating an unmanageable volume of false alarms.
Brand differences matter less than failure modes—until data access gets in the way
Many physical degradation mechanisms cross vendor boundaries. Bearing damage, lubrication problems, imbalance, overheating, and electrical deterioration are not unique to a particular equipment manufacturer. Depending on the asset and fault, vibration, temperature, motor current, pressure, or lubricant analysis can provide useful evidence of developing trouble.
That makes multi-vendor predictive maintenance technically feasible. However, similar failure mechanisms do not guarantee interchangeable models. A high-speed spindle and a low-speed gearbox may both contain bearings, yet their useful signal characteristics, measurement requirements, and operating patterns differ substantially.
Even apparently similar pumps can behave differently because of mounting conditions, process fluids, speed control, and duty cycles. A model that flags an unusual vibration pattern on one installation may be reacting to normal process variation on another.
Standardize the monitoring framework, not every diagnostic assumption. Asset identification, timestamps, data quality checks, and maintenance workflows can be shared. Baselines, relevant features, and alert thresholds may need to remain specific to an equipment family or individual machine.
It also helps to distinguish condition monitoring from prediction. Detecting an abnormal signal is useful, but it does not automatically establish the cause or estimate remaining useful life. Precise failure-time predictions require stronger evidence than a basic anomaly alert.
Where interoperability actually breaks down
Connectivity is the visible challenge. Data meaning is often the harder one. Equipment may expose information through OPC UA, Modbus, proprietary interfaces, or an OEM cloud service. Supporting those interfaces helps, but it does not ensure that the platform receives the measurements needed for a particular diagnosis.
For example, an interface may provide overall vibration values but not raw waveforms. Those summary values can support trending, while some bearing diagnostics require higher-frequency measurements and more detailed analysis. A gateway cannot recover information that the original acquisition system never captured.
Naming and measurement conventions also create problems. One controller may report temperature in Celsius, another in Fahrenheit. Pressure may be absolute or gauge. A tag called “motor load” may represent different quantities across machines. Without checking units, definitions, scaling, and calibration, a clean-looking dashboard can conceal misleading comparisons.
Timing deserves similar attention. Measurements used together should have sufficiently aligned timestamps for the analysis. Missing samples, communications interruptions, and delayed uploads need explicit handling; otherwise, a data outage may look like an equipment event.
Access rights can be just as restrictive as technology. Before selecting a platform, confirm which diagnostic channels are available, whether access requires additional licenses, and whether the equipment supplier permits third-party connections. These details should be established from technical documentation and contract terms, not assumed from a compatibility logo.
Choose an integration route around the asset, not the software demo
Existing machine data is often the sensible starting point. Controller signals, historian records, alarm logs, and production-state information may already describe how an asset operates. Reusing them avoids unnecessary instrumentation, provided their quality and sampling characteristics suit the intended failure detection.
Retrofit sensors offer another route for legacy equipment or machines with restricted diagnostics. Independent vibration, temperature, or current measurements can reduce dependence on proprietary interfaces. Sensor placement, mounting, environmental protection, power supply, and maintenance requirements still need engineering review. An accessible mounting point is not necessarily a useful measurement location.
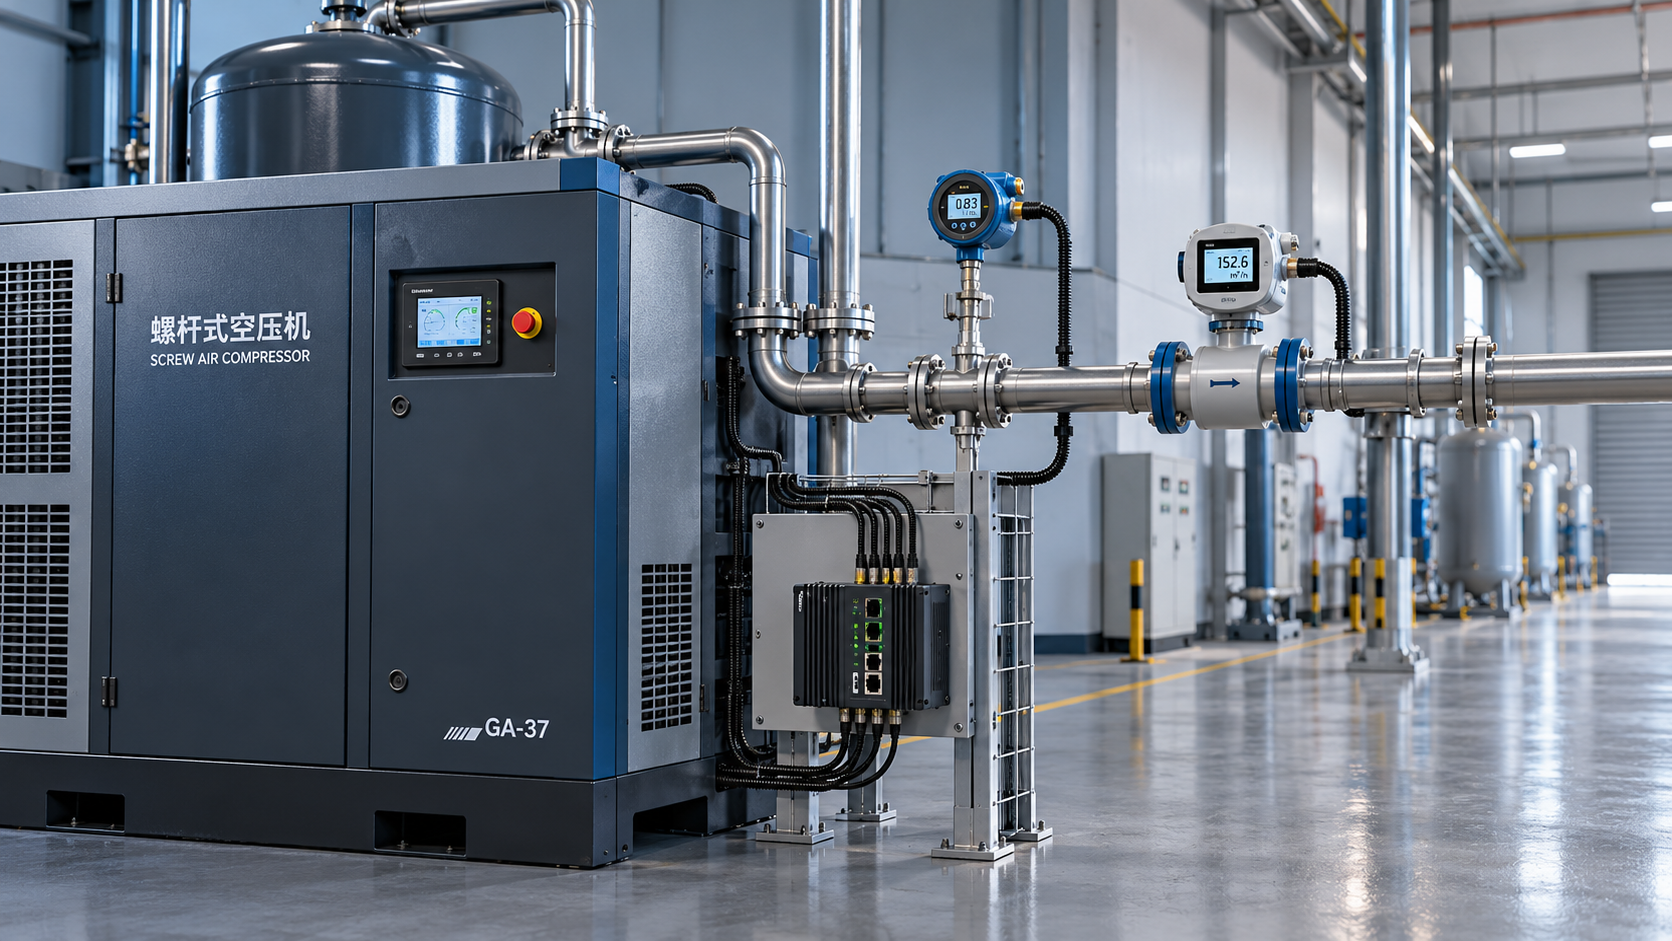
A hybrid arrangement may be more appropriate than either extreme: external sensors capture condition signals, controller data supplies speed and load, and maintenance records provide context. Edge processing can extract features close to the equipment, while a central platform supports fleet visibility and work management.
A practical data path is: equipment signals and operating context, followed by validated collection and normalization, then condition analysis, human review, and a maintenance action. Inspection findings should return to the system so that future alerts can be assessed against actual outcomes.
This architecture separates equipment connectivity from analytics and workflow. It makes individual components easier to replace, but it does not eliminate integration work. Responsibility for tag mapping, sensor upkeep, connector updates, and data quality must remain explicit.
Why a single model rarely fits the entire fleet
Operating context can change a signal as much as degradation does. A compressor under heavy demand, a pump approaching a different process condition, or a spindle machining a new material may look different without being faulty. Models that ignore these conditions can turn ordinary production changes into maintenance alerts.
Grouping assets by mechanical design, speed range, duty, and failure mechanism is usually more useful than grouping them only by manufacturer. Within each group, analysis may need to account for operating states such as startup, steady operation, idle periods, and shutdown.
Historical records also have limits. Maintenance logs may record “bearing replaced” without explaining whether it failed, was replaced preventively, or was removed during another repair. These distinctions affect model training and validation. Sparse failure examples can make supervised prediction difficult, especially for rare but serious faults.
In those circumstances, condition trending, engineering rules, and anomaly detection may be more defensible than a precise remaining-life estimate. Transfer learning can sometimes reuse knowledge across related assets, but its performance still needs testing on the receiving equipment.
Maintenance itself changes the baseline. Replacing a bearing, realigning a drive, or moving a sensor can alter measured behavior. Record those interventions and review the baseline afterward. Otherwise, the system may interpret a repaired machine as unfamiliar or gradually learn a deteriorating condition as normal.
Make suppliers prove useful coverage, not just connectivity
A vendor-neutral platform should be evaluated through evidence tied to your installed equipment. A long list of supported brands is less informative than a clear explanation of what can be measured, which faults can be assessed, and where limitations remain.
- Request model-level compatibility details. Confirm controller versions, accessible signals, sampling constraints, required licenses, and any need for additional hardware.
- Ask what an alert actually means. Does it indicate unusual behavior, identify a likely fault, or estimate remaining life? Ask how uncertainty and supporting evidence are presented.
- Check portability. Establish whether raw data, derived features, alert histories, and asset mappings can be exported in usable formats. Data ownership alone does not guarantee practical access.
- Assign support responsibility. Determine who resolves problems when an OEM firmware change disrupts a connector or an analytics update changes alert behavior.
- Review operational security. Examine network segmentation, authentication, remote access, patching, and offline behavior. Monitoring should not introduce unnecessary control-system exposure.
Cross-border deployments add questions about hosting locations, service availability, and permitted data transfers. For healthcare-related or other regulated environments, monitoring changes may also require formal change control or validation. Confirm obligations against the specific application and local requirements rather than relying on general vendor assurances.
Build a pilot that tests the difficult conditions
A pilot limited to the newest, easiest-to-connect machines proves little about a mixed fleet. Include representative differences: equipment age, controller type, variable duty, and at least one asset with meaningful access constraints. Selection should still be guided by failure consequences and the availability of a practical maintenance response.
Define the target failure modes before installation. Specify what evidence would support an alert, how much warning the maintenance team needs, and what action would follow. Warning time is useful only if it accommodates inspection, spare-parts availability, and a suitable maintenance window.
Evaluate usable data availability, false-alert burden, missed confirmed events where observable, and the proportion of alerts that lead to justified action. Aggregate “accuracy” can be misleading when failures are rare. If no relevant failure occurs during the pilot, do not treat that as proof of predictive performance.
Historical replay and engineering review can supplement live testing, with their limitations documented. Maintenance findings should be captured consistently, including inspections that find no defect. Without that feedback, neither the supplier nor the plant can reliably distinguish helpful warnings from noise.
Cost assessment should include connectors, installation, licenses, cybersecurity review, integration with the computerized maintenance management system, and ongoing model support. Compare these costs with specific maintenance decisions improved—not an assumed percentage reduction in downtime.
The decision is about maintainability, not brand uniformity
Multi-vendor predictive maintenance works when useful signals can be obtained, interpreted in operating context, and converted into credible action. It works less well when critical measurements are inaccessible, degradation offers little warning, or the organization cannot respond to alerts. Some low-consequence assets may remain better suited to scheduled maintenance or run-to-failure.
TradeNexus Pro – Global B2B Intelligence (TNP), operating through chinaspecialmetal.com, approaches technology evaluation through practical industry and supplier analysis. Across advanced manufacturing, green energy, smart electronics, healthcare technology, and supply chain SaaS, the relevant distinction is between a supplier’s claimed capability and the evidence a buyer needs for a deployment decision.
Before committing to fleet-wide rollout, assemble an asset register, accessible-signal inventory, failure-mode priorities, and written pilot acceptance criteria. Those documents reveal whether a proposed solution can handle your equipment differences—and which differences still require additional engineering.
Get weekly intelligence in your inbox.
No noise. No sponsored content. Pure intelligence.
 Oct 25, 2026Teradyne Robotics and Sereact Partner on AI-Powered Returns AutomationTeradyne Robotics and Sereact Partner on AI-Powered Returns Automation
 Oct 25, 2026Smart Warehousing Integration: How to Connect Robots to an Existing WMSSmart Warehousing Integration: How to Connect Robots to an Existing WMS
 Oct 24, 2026Tesla Q3 2026 Storage Deployments Rank Second Highest as Revenue Falls 16%Tesla Q3 2026 Storage Deployments Rank Second Highest as Revenue Falls 16%
 Oct 24, 2026Freight Forwarding Services Pricing: Comparing Quotes Beyond Base RatesFreight Forwarding Services Pricing: Comparing Quotes Beyond Base Rates
 Oct 23, 2026IndexBox Issues Off-Grid Solar Outlook to 2035, Forecasting 8.2% CAGRIndexBox Issues Off-Grid Solar Outlook to 2035, Forecasting 8.2% CAGR
 Oct 23, 2026NSF/ANSI 49 Biosafety Cabinets: Product Certification vs. Field TestingNSF/ANSI 49 Biosafety Cabinets: Product Certification vs. Field Testing
 Oct 22, 2026Mitsubishi Electric Develops Industry-First Humanoid Robot–CNC Machining SystemMitsubishi Electric Develops Industry-First Humanoid Robot–CNC Machining System
 Oct 22, 2026Aerospace Aluminum Machining: How to Control Distortion in Thin-Wall PartsAerospace Aluminum Machining: How to Control Distortion in Thin-Wall Parts
 Oct 21, 2026Genesis Energy commissions 200 MWh battery storage system at HuntlyGenesis Energy commissions 200 MWh battery storage system at Huntly
 Oct 21, 2026Buying AMI Smart Meters Wholesale: Compatibility Checks and Total CostsBuying AMI Smart Meters Wholesale: Compatibility Checks and Total Costs
 Oct 20, 2026Werner Enterprises Issues Q3 Earnings Warning as Costs RiseWerner Enterprises Issues Q3 Earnings Warning as Costs Rise
 Oct 20, 2026Are Digital Twins Viable for SMEs? Costs, Use Cases, and Data RequirementsAre Digital Twins Viable for SMEs? Costs, Use Cases, and Data Requirements
 Oct 19, 2026Choosing a Wholesale Servo Motor Exporter: Traceability and Warranty ChecksChoosing a Wholesale Servo Motor Exporter: Traceability and Warranty Checks
 Oct 18, 2026Syringe Manufacturing Equipment: Evaluating Throughput and Assembly AccuracySyringe Manufacturing Equipment: Evaluating Throughput and Assembly Accuracy
 Oct 17, 2026Air Freight Forwarding Services: How to Compare Quotes for Urgent ShipmentsAir Freight Forwarding Services: How to Compare Quotes for Urgent Shipments
 Oct 16, 2026Wholesale Solar Panels: How to Compare Bulk Quotes by Total Landed CostWholesale Solar Panels: How to Compare Bulk Quotes by Total Landed Cost
 Oct 15, 2026Supply Chain Intelligence for Sourcing: How to Vet New SuppliersSupply Chain Intelligence for Sourcing: How to Vet New Suppliers
 Oct 14, 2026How to assess a smart manufacturing systems integrator for retrofitsHow to assess a smart manufacturing systems integrator for retrofits
 Oct 14, 2026How energy costs shape smart manufacturing investment in EuropeHow energy costs shape smart manufacturing investment in Europe
 Oct 14, 2026How skills shortages slow smart manufacturing in Southeast AsiaHow skills shortages slow smart manufacturing in Southeast Asia
 Oct 14, 2026How CNC wire-cut machining maintains tight tolerances in thick partsHow CNC wire-cut machining maintains tight tolerances in thick parts
 Oct 14, 2026Can automated feeding stabilize metal forming in smart factories?Can automated feeding stabilize metal forming in smart factories?
 Oct 14, 2026Can CT inspection detect internal defects in metal additive parts?Can CT inspection detect internal defects in metal additive parts?
 Oct 14, 2026When does additive manufacturing reduce lead time for spare parts?When does additive manufacturing reduce lead time for spare parts?
 Oct 14, 2026How production volume affects ROI on an automated painting lineHow production volume affects ROI on an automated painting line
 Oct 14, 2026What data does manufacturing bottleneck analysis consulting need?What data does manufacturing bottleneck analysis consulting need?
 Oct 14, 2026When should you hire a consultant for manufacturing bottlenecks?When should you hire a consultant for manufacturing bottlenecks?